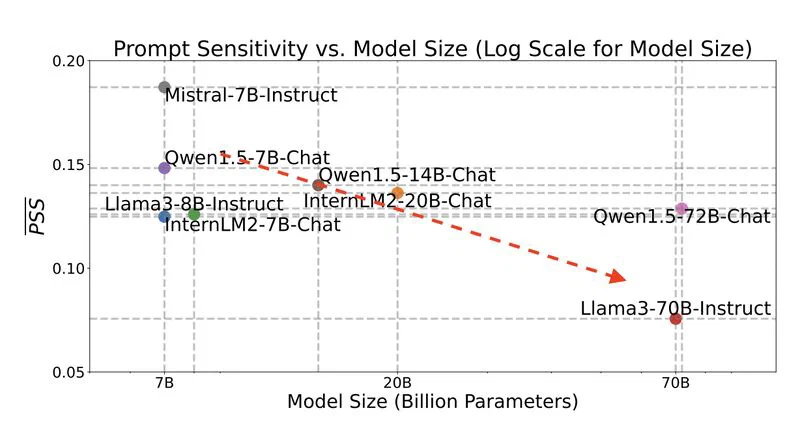
#Prompt wording matters less with larger models
Stop overthinking how you word your ChatGPT prompts for general questions. With the latest models, it doesn’t matter anymore.
A new study shows that the bigger LLMs get, the less they care about purely cosmetic variations in the prompt.
In plain terms: polishing the phrasing of your question won’t do much for the quality of the answer. Same for instructions like “Act as a math teacher”.
One trick still works, though: giving a few examples. In prompt engineering, this comes in three flavors:
- Zero-shot: no example at all
- One-shot: one example of an input and the expected answer
- Few-shot: a handful of examples, usually 2 to 5
The gains are biggest on complex questions, creative tasks and coding help.
Smaller models (under 20B parameters), the ones built to run locally, are a different story: they still react to the exact wording of the prompt.
Last year, “prompt engineer” looked like the job of the future. A year from now, who knows whether the specialty will still exist.
Link to the study: arXiv 2410.12405